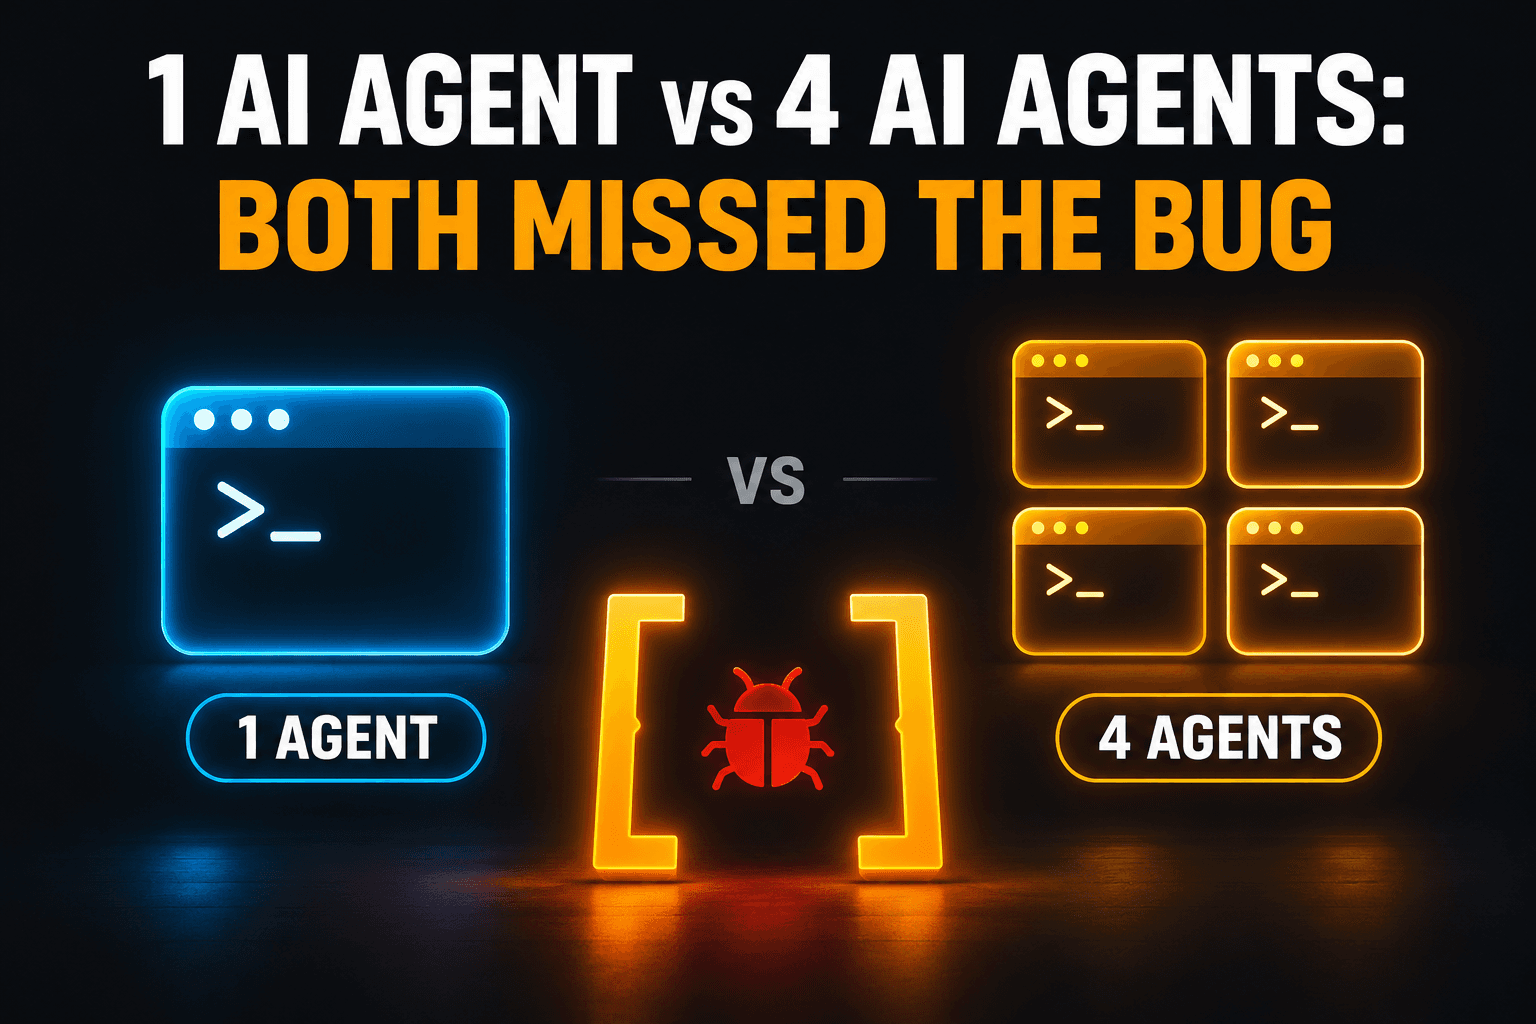
We took a real bug from our own product, MastReach, and gave it to two AI setups: one coding agent working alone, and a team of four agents running side by side in Herdr, the open-source tool that puts many coding agents in one control room. Same bug, same model, same rules, one stopwatch.
Both said "fixed". Both were wrong. The real cause was hiding in two characters, and neither setup ever saw them. This post walks through the race, the real detective work that found the bug, why more agents didn't help, and five habits that would have caught it on day one.

Prefer to watch? The full 5-minute video is on our YouTube channel: 1 AI Agent vs 4 AI Agents: Both Missed the Bug. Here's What Found It.
The bug: a paid answer, thrown away
On 2 November, our teammate Rishav asked MastReach to write comment ideas for a post. The screen said: No comment options generated.
The AI had already answered. The call was billed (about Rs 0.26). And our own code threw the answer away. Worse, nobody could reproduce it: we rebuilt the post and ran the writer five times, and got five perfect answers.
The race: 1 agent vs a 4-agent Herdr team
To make it fair, we rewound the code to the commit just before the real fix and locked away the 45 tests that came with that fix. Both sides got the original bug report, the same model and the same rules: no internet, no secrets, and no live AI calls.
Measure | Run A · one agent | Run B · Herdr team of 4 |
|---|---|---|
Prompt to commit | 5:12 | 14:49 (about 2 min of it blocked) |
Output tokens | ~25K | ~149K |
Hidden tests passed (of 45) | 23 | 23 (19 passed before any fix) |
Found the real cause | No | No |
Same score, about 3x the time and 6x the tokens for the team. Herdr did earn one real point: its sidebar flagged the lead agent as blocked within two minutes, which saves real time when several long jobs are running.
How the real cause was actually found
Not with Herdr. The real fix was written on 2 November, six days before we installed Herdr for this test. Here is the investigation, from the fix's own commit message.
1. The missing ingredient
Our five tries used a rebuilt post. Rishav's real post already had comments from other people on it, and those comments go into the prompt. With them in, the same request failed 4 times out of 12. Without them: 0 out of 5.
2. The raw answer
This time every raw answer was saved. We had asked the model for one object with a list of options inside. On the failing calls, the model wrapped the whole answer in one extra pair of square brackets:
[
  {
    "touches": "Scale breaks the founder first.",
    "options": [
      { "comment": "Scale usually means trading…" },
      { "comment": "The hardest part is letting go…" },
      { "comment": "…" }
    ]
  }
]
3. The parser's assumption
Our parser, llm.as_list, saw a square bracket and assumed: this must be the list of options. So it found one item, the wrapper. The wrapper has no comment in it, so there were no options. Three good comments, already paid for, were thrown away one level down.
4. The fix: 15 lines in one file
If the list holds objects that carry the options, open them first:
if isinstance(got, list):
    wrapped = [it[key] for it in got
               if isinstance(it, dict) and isinstance(it.get(key), list)]
    if wrapped:
        return [x for lst in wrapped for x in lst]
    return got
Then 12 real calls again: 3 still came back wrapped, and all 12 gave three comments. To prove the tests were real, the fix was broken on purpose four different ways, and the tests caught all four. The follow-up retry code got 13 planted bugs, and all 13 were caught.
Why both AI setups missed it
No evidence. Our test rules said no live AI calls, and the brackets only appear in a live call with the real prompt.
Wrong file. Both runs changed
cto_outreach.py, where the error message lives. The bug lived inllm.py.Trusted the first guess. Both accepted the bug report's first theory. Herdr's investigator tested 13 answer shapes, but not the wrapped one.
More agents don't see more. They see the same evidence, more times.
5 habits that would have caught it on day one
When an AI answer fails, log the raw answer. The first 300 characters are enough. You already paid for it.
Reproduce with the full, real prompt, not a cleaned-up copy. Context changes the shape of the answer.
Never trust the shape of AI JSON. Accept bare, wrapped and single-item forms, and test each one.
Break your own fix on purpose. If a planted bug doesn't turn a test red, your tests aren't guarding anything.
Judge AI agents on a bug you already fixed. Rewind to the commit before the fix, hide the fix's tests, and grade with them.
If your AI bills are also leaking through retries and wasted calls, our 7-line AI bill audit pairs well with habit 1, and the hidden ways your AI product leaks money covers the rest.
So, is Herdr worth it?
For work that truly splits, yes: four codebases, four agents, one screen, and a red light the moment one gets stuck. For one small bug, one agent with the right evidence beats four agents without it. We measured one small, single-file bug; parallel, multi-repo work is our next test.
Get the free playbook
We put the whole workflow in a free 12-page PDF: the install steps, the exact Herdr commands, the prompts we gave each agent, our safety settings, the hidden-test setup, every result and these five habits. Email rianinfotech0201@gmail.com or message us and we'll send it to you.
Join the conversation
▶ Watch the video on YouTube: youtube.com/watch?v=x_E0wIC3_ro
💬 Comment on the LinkedIn post: Rian Infotech on LinkedIn
Frequently Asked Questions
Rishav Shankar
Rishav Shankar is a calm-tech architect who blends AI, engineering, and psychology to design systems that think before they act. He builds products that turn complex human problems into intuitive digital experiences, redefining how founders and teams operate. At the intersection of automation, strategy, and imagination, Rishav is creating the future one intelligent workflow at a time.
Comments
Loading...